原文:arXiv:1901.00370 · Umuroglu et al., TRETS 2019
1.Intro
对 BISMO: A Scalable Bit Serial Matrix Multiplication Overlay for Reconfigurable Computing 的改进,引入了 P2S 模块 + FGPA 上的优化 + 阶段调度的优化 + LUT 的优化
2.Background: Bit-Serial
改进的思想:内存提供的位顺序与加速器期望接收到他们的顺序要尽量一致,保证内存带宽尽量被高效利用。 传统方法计算的时候一个元素的所有 bit 都是连续的,因为所有 bit 是在一次处理过程中被同时用到的,data layout 类似;基于 Bit-Serial 的方法每次处理的是很多元素的同一个位,输入的时候就要尽量保证 data layou 变成的形式。 为了实现这种 bit-serial 的 data layout,引入了 parallel-to-serial 的新模块。
3.The Bit-Serial Matrix Multiplication Overlay
3.1. Overall
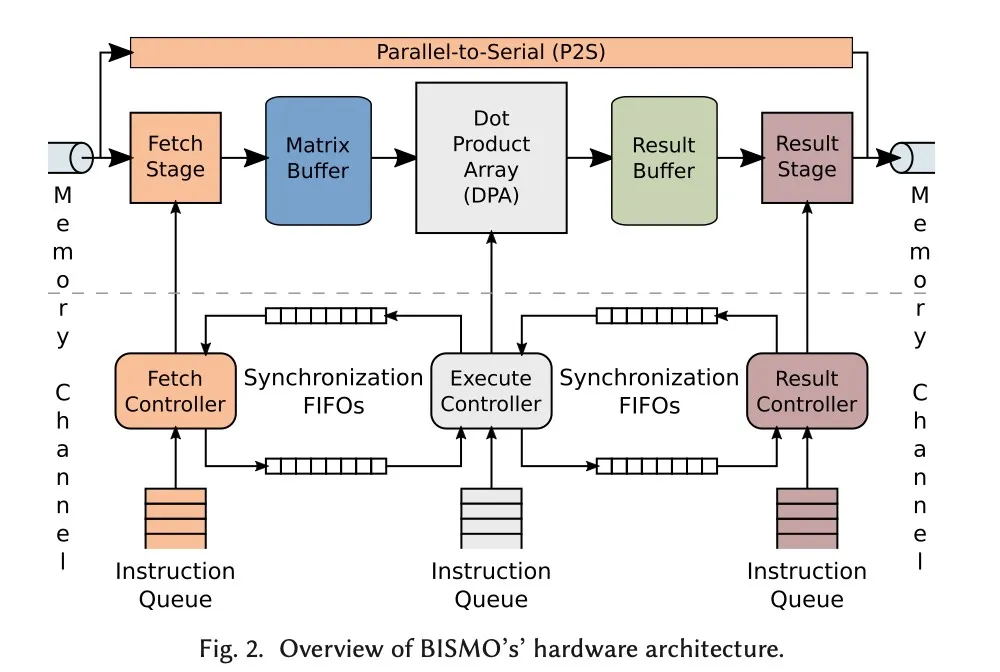
新结构里面多了一个 P2S 模块,“as an optional, standalone accelerator”。
3.2. the Dot Product Unit DPU
电路上的优化,没看懂
3.3. Bit-Parallel to Bit-Serial Matrix Transformation
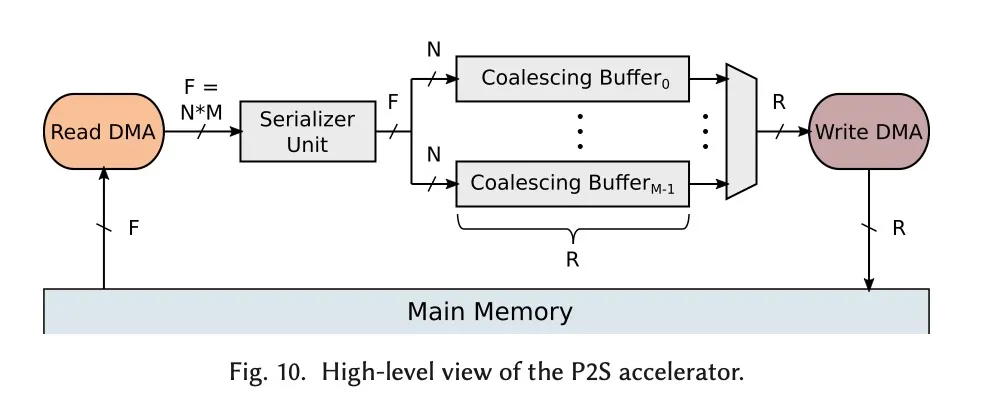
“The total number of coalescing buffers defines the maximum supported precision M of the bit-parallel input matrix and is specified at synthesis time.” DMA 读出来的数据按 bit 放入 Buffer 中,就是第 i 位,M 的大小决定了 P2S 模块支持的最大精度。
3.4. Cost Model
和 BISMO 原文一样从 LUT 和 BRAM 两个方面分析
3.5. Programming BISMO
加了一个 Running P2S 指令,P2S 是从 DRAM 读出再写回 DRAM,和 BISMO 本身完全没有交互。